Domain knowledge infrastructure

The layer where managed domain knowledge for humans and agents lives

Nava is the platform where a company's domain knowledge is centrally managed by the people who own it, and optimally structured for consumption by AI agents. Experts author, review and approve. Agents sync the approved version and run on it.

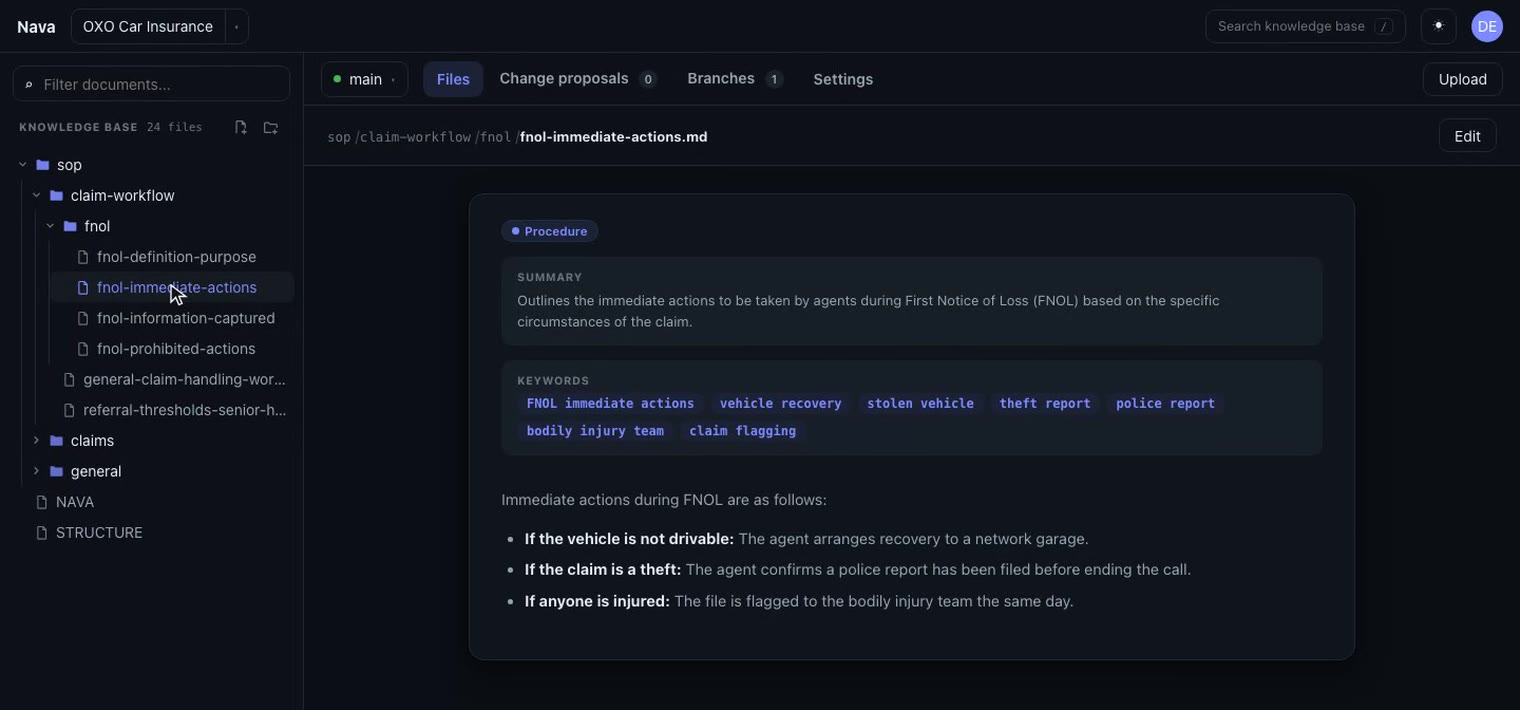
nava · claim workflow › first notice of loss › immediate actions
A knowledge document open in Nava: folder tree on the left, and the document with its type, generated summary and keywords above the body

Domain knowledge is encapsulated in structured documents with enriched metadata. Optimal for human management and agentic consumption

What Nava is

One system of record. Two audiences: humans and agents.

Companies want agents to autonomously complete real work — claims processing, complaint resolution, customer support. The bottleneck is usually not the model. It is the company's own domain knowledge, scattered across many heterogeneous sources of truth, that agents need to find and consume.

human-facing

The system of record for operational knowledge

Domain experts write, edit, review and approve standard operational knowledge in a GitHub-meets-Notion interface. Every change is versioned and reviewed before it becomes approved. AI assists throughout — it ingests existing documents, structures them into units of operational knowledge, finds missing links, and flags contradictions for the human reviewer.

agent-facing

The same knowledge, structured for machines

Domain knowledge is shaped for optimal search and consumption by LLM-based agents:

  • a clean, consistent folder structure that plays to agents' strength at navigating filesystems
  • documents enriched with metadata — related documents, keywords, summaries
  • a vector database kept in sync with every approved change

Our custom MCP server lets agents sync the latest state of the knowledge and access it efficiently — fast and precise retrieval, reproducible behaviour, version-controlled deployments.

We are not building another agent platform. Customers keep their own agents. We offer the AI-assisted platform for the governed source of truth those agents run on.

Why we're building it

Structured domain knowledge is becoming the new code.

Nava comes out of years of building agents that assist or replace humans in real operations, especially across insurance processes. The same lesson recurred on every project: the model is not the bottleneck — the domain knowledge is.

A single operation can run on thousands of operational guidelines. In the best case they are nominally documented in one place. Usually the knowledge is scattered across heterogeneous documentation tools, email histories, and even individuals' personal notes and minds. Collecting, de-conflicting and maintaining that knowledge base is the major bottleneck to the state where agents autonomously substitute humans in end-to-end processes.

As agents execute more business processes, the procedures humans maintain become the source code for those agents. But today those procedures live in Confluence, Notion, Word, SharePoint, email, and people's heads. Teams bolt a vector database on top and hope retrieval fixes it. It does not — the source knowledge is still inconsistent, unreviewed, unauditable, and not structured for reliable machine consumption.

Every company that runs agents on real operations will need somewhere to write, review, version, test and serve the procedures those agents follow. We are building the tool we wished we had.

Product

Governed by humans. Structured for machines.

One knowledge base, two surfaces.

write & govern

A single place your experts actually maintain

The people who own a process write and edit it in a familiar editor. Every edit — typed by a person or proposed by AI — goes through review and approval before it is published, and the full history of who changed what, and why, is kept.

structure for machines

Units of knowledge, not document chunks

Knowledge is held as self-contained, cross-linked documents enriched with metadata — type, summary, keywords, related documents — laid out in a clean, consistent structure. AI does the heavy lifting of getting your existing material into that shape.

serve your agents

Approved knowledge, delivered to your agents

Your agents pull the published knowledge and work from it directly: navigate it, read it, follow links, search by meaning, filter by metadata. Available as an SDK and an MCP server — you keep your own agents.

How it works

From scattered documents to agent-ready knowledge

Six capabilities, from the first upload to the answer your agent gives.

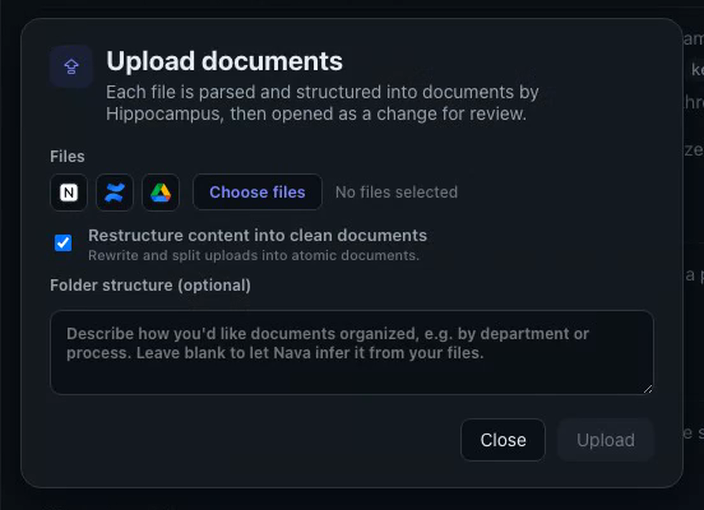
Nava's upload dialog, with connectors for Notion, Confluence and Google Drive next to a file picker
for domain experts ai-assisted ingestion

Drop in the mess. Get back structure.

Connect your documentation tools or batch-upload the files you already have. Nava reads them and uses AI to turn them into structured, cross-linked units of operational knowledge, with metadata and a proposed folder structure.
for domain experts ai consistency checks

A second reader that never gets tired.

Every proposed change is checked against related knowledge for contradictions, ambiguity and missing links. The flags are advisory — surfaced to the human reviewer, never enforced.

for domain experts authoring & version history

Every version kept. Every change traceable.

Editing is as simple as editing a document, and nothing is ever silently overwritten: each edit becomes a proposed change with its own history. Only approved work becomes the version your agents see.

for domain experts human review workflow

Nothing reaches an agent unreviewed.

Every proposed change — written by a person or produced by AI — passes human review before it is published. Who approved what, when, and why is part of the record.

for agents search indexes, always in sync

Indexes that are never stale.

An index of every document's metadata and a semantic index of its meaning, both built from the approved documents and rebuilt the moment a change is published. The documents stay the source of truth; the indexes follow.

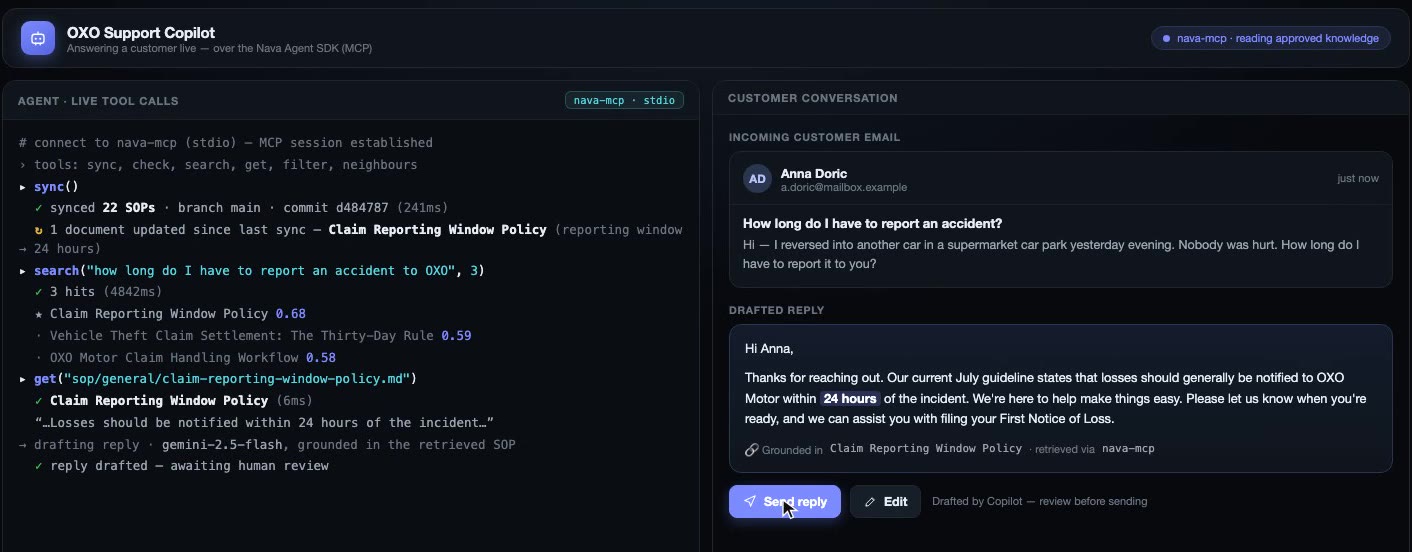
An email-support agent that pulled the published knowledge, searched it, and drafted a reply grounded in the document it found
for agents agent sdk & mcp server

Pull it. Search it. Answer with it.

Your agents pull the published knowledge — or any earlier published version — onto their own machine, then navigate it, read it, follow links, search by meaning and filter by metadata. Fast, precise, and grounded in a version you can point at.

About

Built by engineers who hit this wall on every project

Nava was founded in Zurich in 2026 by machine learning engineers who have built and shipped agentic systems in production. We experienced the problem Nava solves first-hand: the agent was always the easy part — collecting, de-conflicting and maintaining the domain knowledge it needed was the wall. We are building the layer we kept wishing existed.

Zurich, SwitzerlandFounded 2026
Design partnersOnboarding now

Book a demo

See it on your own knowledge

If your organization runs on large bodies of operational knowledge — insurance, banking, BPO, customer service — and you are putting agents on real work, we would like to talk.

Tell us what you run on today and we will show you what your agents would actually consume.